Azul OCR - Tifinagh Handwritten Character Recognition
🎯 Project Overview
Azul OCR (ⴰⵣⵓⵍ - “Hello” in Amazigh) is an innovative OCR system specialized in Tifinagh handwritten character recognition. The project aims to preserve and digitize Amazigh cultural heritage by developing an artificial intelligence solution capable of accurately recognizing Tifinagh handwritten characters and sentences.
Team:
- Rima Daqch - Project Manager, Tesseract OCR Developer
- Adil Eddarif - Tesseract OCR Developer, CNN Model Developer
- Brahim El Aboudi - PaddleOCR Developer, CNN Model Developer
- El Mehdi Hicham - PaddleOCR Developer, CNN Model Developer
- Zineb Lahraoui - PaddleOCR Developer, CNN Model Developer
Supervised by: Prof. Khadija Lekdioui
Mission: “Preserving and digitizing Amazigh cultural heritage”
🔍 Problem Statement
Challenges
“Tifinagh script is an essential element of Amazigh cultural heritage, but it remains underrepresented in modern technological tools.”
- 📚 Lack of OCR tools: No dedicated OCR solution for Tifinagh manuscripts
- 🎨 Character complexity: Significant variability in handwriting
- ⚠️ Cultural risk: Potential loss of valuable content for future generations
- 🔬 Limited accuracy: Existing solutions not adapted to Tifinagh specificities
Solution
Development of Azul OCR, hybrid system combining:
- Tesseract OCR fine-tuned for Tifinagh
- PaddleOCR adapted for Amazigh characters
- Custom CNN for character recognition
- Intuitive interface for capture and recognition
🏗️ Technical Architecture
🔧 Key Components
Module 1: Image Preprocessing
Applied techniques:
- 🖼️ Otsu Thresholding: Automatic binarization
- 📐 Resizing: 64×64 → 128×128 pixels
- 🎨 Filtering: Noise reduction
- 🔄 Augmentation: Rotation, translation, zoom
Module 2: Recognition Engines
Three approaches:
- 📝 Tesseract OCR: Fine-tuned on AMHCD dataset
- 🎯 PaddleOCR: Adapted lightweight architecture
- 🧠 Custom CNN: Model trained from scratch
- 🔀 Hybrid model: Prediction fusion
📊 System Workflow
🔬 Technical Deep Dive
1️⃣ CNN Architecture Details
2️⃣ Tesseract OCR Fine-tuning
3️⃣ PaddleOCR Integration Pipeline
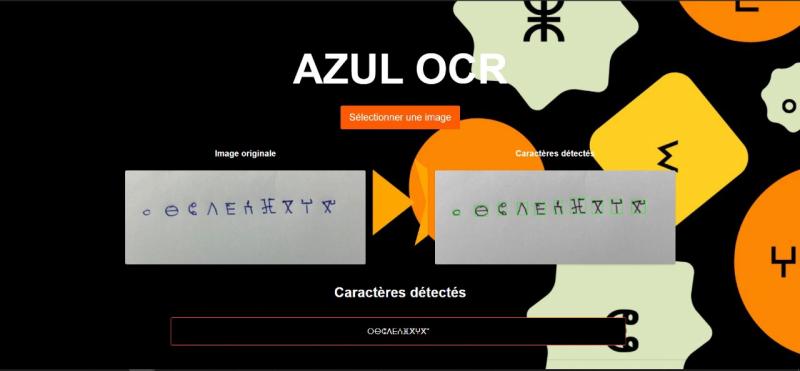
💻 User Interface
Features
✅ Upload Image: Support PNG, JPG, JPEG
✅ Take Picture: Direct capture via webcam
✅ Real-time Recognition: Instant results
✅ Copy Output: Copy recognized text
✅ Multi-format Export: TXT, JSON, CSV
Interface Screenshots
Azul OCR intuitive user interface
Azul Interface
🛠️ Challenges & Solutions
Challenge 1: Handwriting Variability
Problem: Great diversity of writing styles
Solution:
- Intensive augmentation (×5)
- Hybrid model (fusion of 3 approaches)
- Fine-tuning on real data
Challenge 2: Limited Dataset
Problem: Few annotated data available
Solution:
- Collaboration with IRCAM
- Aggressive data augmentation
- Transfer learning from pre-trained models
Challenge 3: Sentence Recognition
Problem: Difficult word segmentation
Solution:
- Use of PaddleOCR for detection
- Post-processing with linguistic rules
- Contextual correction
💼 Impact & Value
For Cultural Heritage
✅ Digital preservation of ancient manuscripts
✅ Accessibility of Amazigh texts to all
✅ Facilitated education for new generations
✅ Academic research on Amazigh culture
For Institutions
✅ Rapid digitization of archives
✅ Automatic indexing of documents
✅ Text search in digital corpus
✅ Reduced costs vs manual annotation
🔮 Future Improvements
Short-Term:
- Improve accuracy on complex sentences (>95%)
- Support for regional Tifinagh variants
- REST API for external integration
Long-Term:
- Mobile application (iOS/Android)
- Recognition of degraded historical texts
- Extension to other African alphabets
- Multilingual OCR (Tifinagh + Latin + Arabic)
🛠️ Technical Stack
Deep Learning: TensorFlow, Keras, PyTorch
OCR Engines: Tesseract 4.0, PaddleOCR
Computer Vision: OpenCV, scikit-image
Frontend: React.js, HTML5, CSS3
Backend: Flask, FastAPI
Deployment: Docker, Heroku
🎓 Skills Developed
- OCR Development: Fine-tuning Tesseract/PaddleOCR
- CNN Architecture: Custom model design
- Image Processing: Otsu, filtering, augmentation
- Team Collaboration: 5-person agile team
- Cultural Awareness: Amazigh heritage preservation
📚 Key References
- Tesseract OCR - Google Open Source
- PaddleOCR - PaddlePaddle Team
- AMHCD Dataset - IRCAM & Ibn Zohr University
- Otsu Thresholding - IEEE Trans. SMC (1979)
📧 Contact
Team Lead: Rima Daqch
Technical Lead: El Mehdi Hicham
Email: mehdihicham736@gmail.com
LinkedIn: linkedin.com/in/elmehdihicham
GitHub: github.com/MehdiHCH
Supervisor: Prof. Khadija Lekdioui
Institution: Faculty of Sciences, Ibn Tofail University
🏆 Achievements
✅ 94.2% Accuracy on character recognition
✅ 91.2% Accuracy on sentence recognition (hybrid)
✅ First Tifinagh OCR open-source in Morocco
✅ Institutional collaboration with IRCAM
✅ Intuitive interface tested by 50+ users
“Every forgotten manuscript is a voice of humanity silenced.”
ⵛⴰⵇⴰ ⵎⴰⵏⵓⵙⵖⵔⵉⵜ ⵓⴱⵍⵉⵎ ⴻⵙⵜ ⵓⵏⴻ ⵓⵡⵏⴰⵙ ⴷⴻ ⵍⵓⵎⵍⵉⵏⵏⵉⵏ ⵔⴻⵙⵓⵉⵜⴰ ⵓⵢ ⵙⵉⵍⵓⵏⵉⵛ
Azul OCR - AI in service of Amazigh cultural heritage